GaP: A Graph-as-Policy Multi-Agent Self-Learning Harness for Variational Automation Tasks
Session: CoRL 2026 Spotlight (top 3.4%). Presented in Ken Goldberg's Agentic Robotics talk on Day 3. See the talk notes. Paper: arXiv 2607.05369 by Kaiyuan Chen*, Shuangyu Xie*, et al., with Yuke Zhu, Linxi "Jim" Fan, and Ken Goldberg (UC Berkeley, NVIDIA, Bosch). *Equal contribution. Links: project page, code, docs, and the open robot skills library.
Paper summary (from the Agentic Robotics project page, a secondary source; the paper itself is not yet read)
- Problem: Automation tasks have to keep working across variation in pose, objects, environment, and lighting.
- Method:
- Policy: The policy is a graph of modular skills, such as perception, grasp selection, motion planning, force control, and failure recovery. The skills can include VLA policies.
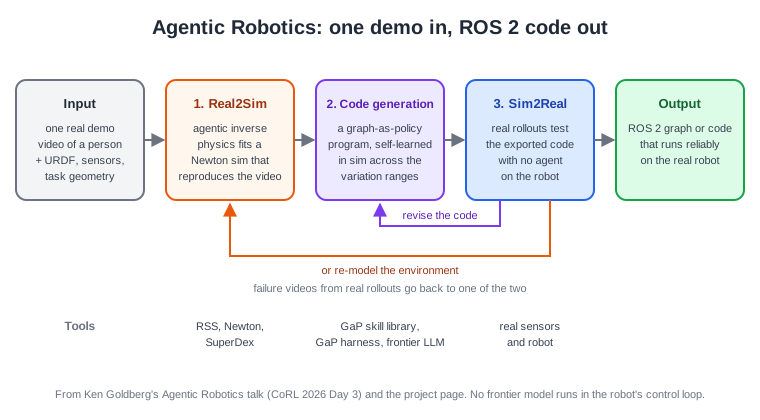
- How it learns: A frontier LLM writes and improves the graph's code in a Newton simulation, using the GaP harness and skill library. Each round runs hundreds of episodes, groups the failures, and rewrites the code. The aim is to maximize success rate and minimize cycle time.
- Deployment: The output is lightweight, ROS 2-compatible code. No frontier model runs in the robot's control loop.
- Results: The project page gives no GaP-specific numbers. The related FlipAnything result is 24.7% → 95.0% success on 24 tools, over 36 policy versions.
Talk notes
- See the Day 3 notes for Goldberg's three-stage pipeline: Real2Sim, then code generation, then Sim2Real.