Day 1: Mon, Nov 9, 2026
Sessions attended
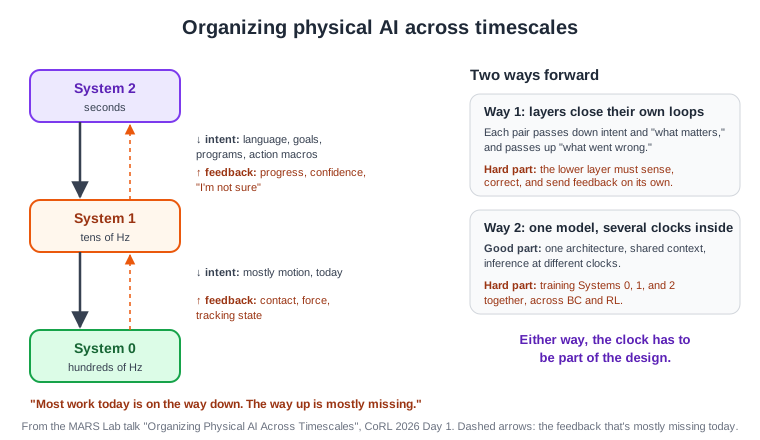
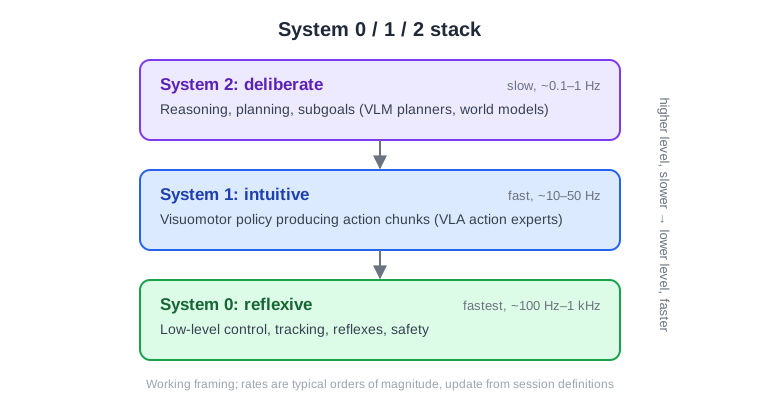
- MARS Lab: Organizing Physical AI Across Timescales (about 10:00 am, from slide photos). Speaker not recorded. Notes in themes/system-0-1-2.md.
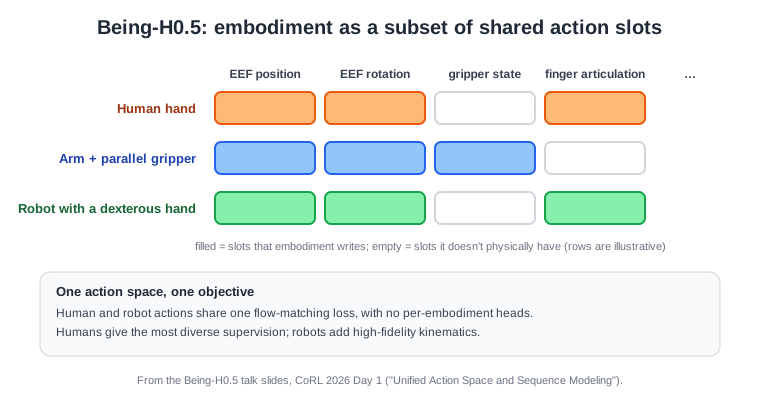
- Being-H0.5 talk (about 10:50 am, from slide photos).
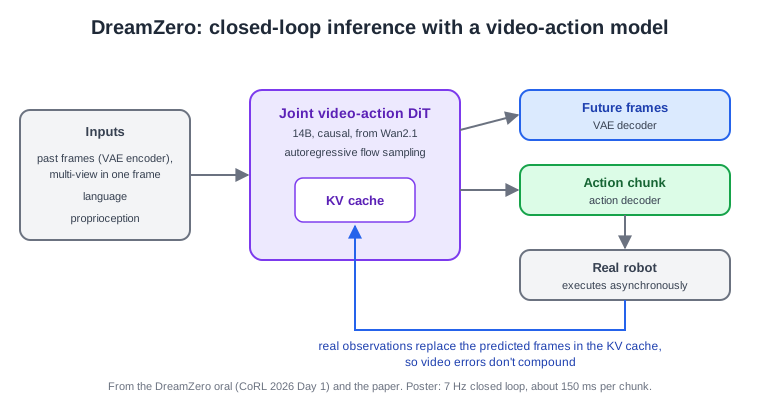
- Oral Session 2: Talk 1, World Action Models are Zero-Shot Policies (slides photographed at 11:11 and 11:14 am)
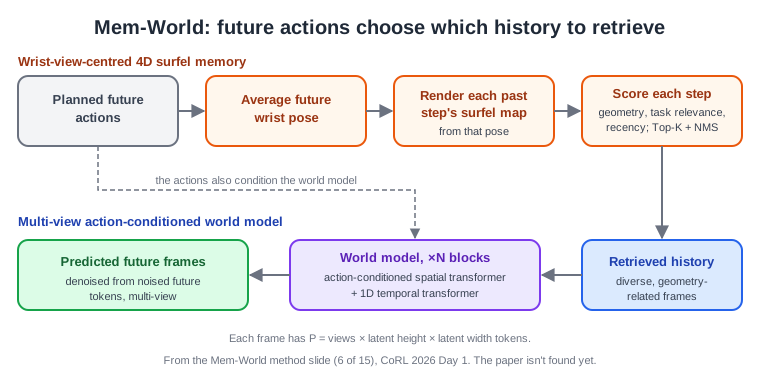
- Mem-World (slide photographed at 11:25 am). Possibly a later talk in Oral Session 2.
- TEMPO oral (11:00 am, Hilton Austin): TEMPO
Papers covered
| Paper | Group | Headline | Status | Links | Weights |
|---|---|---|---|---|---|
| Being-H0.5 | BeingBeyond | 35k h across 30 embodiments with a unified action space; 98.9% LIBERO | abstract | arXiv · page | ? |
| DreamZero | NVIDIA | 14B video model as policy; over 2× generalization vs VLAs at 7 Hz | summarized | arXiv · page · code | ✅ |
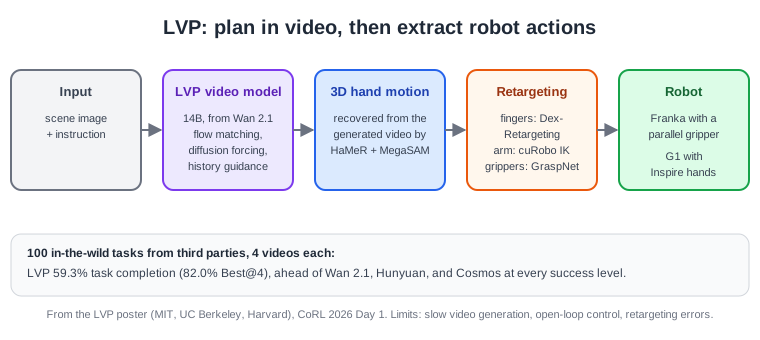
| LVP | MIT, UC Berkeley, Harvard | 14B video planner for zero-shot robot control; 59.3% task completion on 100 third-party tasks vs Wan 2.1, Hunyuan, Cosmos | talk-only | page | ? |
| MemoryVAM | UCLA, UCSD, Utah, Nirvana Robotics | LIBERO-Mem from 5% to 42.5%; 75–80% on real memory tasks | summarized | arXiv · page | ? |
| Mem-World | Future actions pick which history a multi-view world model retrieves, via a wrist-view 4D surfel memory | talk-only | ? | ||
| MolmoBot | Ai2 | Sim-only training; 79.2% real pick-and-place vs 39.2% for π0.5 | abstract | arXiv · page | ? |
| π0.7 | Physical Intelligence | Metadata turns low-quality data from harmful to helpful; zero-shot UR5e shirt folding at teleoperator level | summarized | arXiv · page | — |
| RoboTTT | NVIDIA GEAR, Stanford, UT Austin | 8K-step context at constant per-step cost; 79% vs 42% task completion | summarized | arXiv · page | ? |
| TEMPO | UC Irvine | Motion and command history for +2M parameters; 47.5% to 76.0% average success | summarized | arXiv · page · code | — |
Day 1 themes
Cross-day versions: world models, memory, human data, Systems 0/1/2.
- Scaling along new axes: Data diversity with metadata (π0.7), human video (Being-H0.5, DreamZero), context length (RoboTTT), and simulation scale (MolmoBot).
- Cross-embodiment transfer is now the default goal: Every talk claimed some form of transfer to new robots or zero-shot deployment.
- Video and world models are moving into the policy: DreamZero predicts video and actions together, π0.7 uses a world model for subgoal images, and MemoryVAM adds memory to a video action model.
- Single-frame policies are not enough: RoboTTT (8K-step context), MemoryVAM (episodic memory), TEMPO (motion and action history), and π0.7 (MEM video history) all add temporal context. They differ in cost. TEMPO and RoboTTT keep the cost of each step constant, and MemoryVAM's cost grows with episode length.
Live notes
MARS Lab: Organizing Physical AI Across Timescales
About 10:00 am, from slide photos. Full notes are in themes/system-0-1-2.md.
Being-H0.5
About 10:50 am, from slide photos. Full notes are in papers/being-h05.md.
Oral Session 2, Talk 1: DreamZero
Slides photographed at 11:11 and 11:14 am. Full notes are in papers/dreamzero.md.
Mem-World
Slide photographed at 11:25 am. Full notes are in papers/memworld.md.
Evening posters
Photos taken 5:30–5:53 pm.